Loading...
Subscribe to Our Newsletter
Get the latest updates delivered straight to your inbox.
The ultimate L&D solution for upskilling your workforce.


© 2026 SkillUp MENA, Inc. All rights reserved
Subscribe to Our Newsletter
Get the latest updates delivered straight to your inbox.
The ultimate L&D solution for upskilling your workforce.
© 2026 SkillUp MENA, Inc. All rights reserved

 Share :


eLearning for Egyptian Customer Service Teams: Response Quality
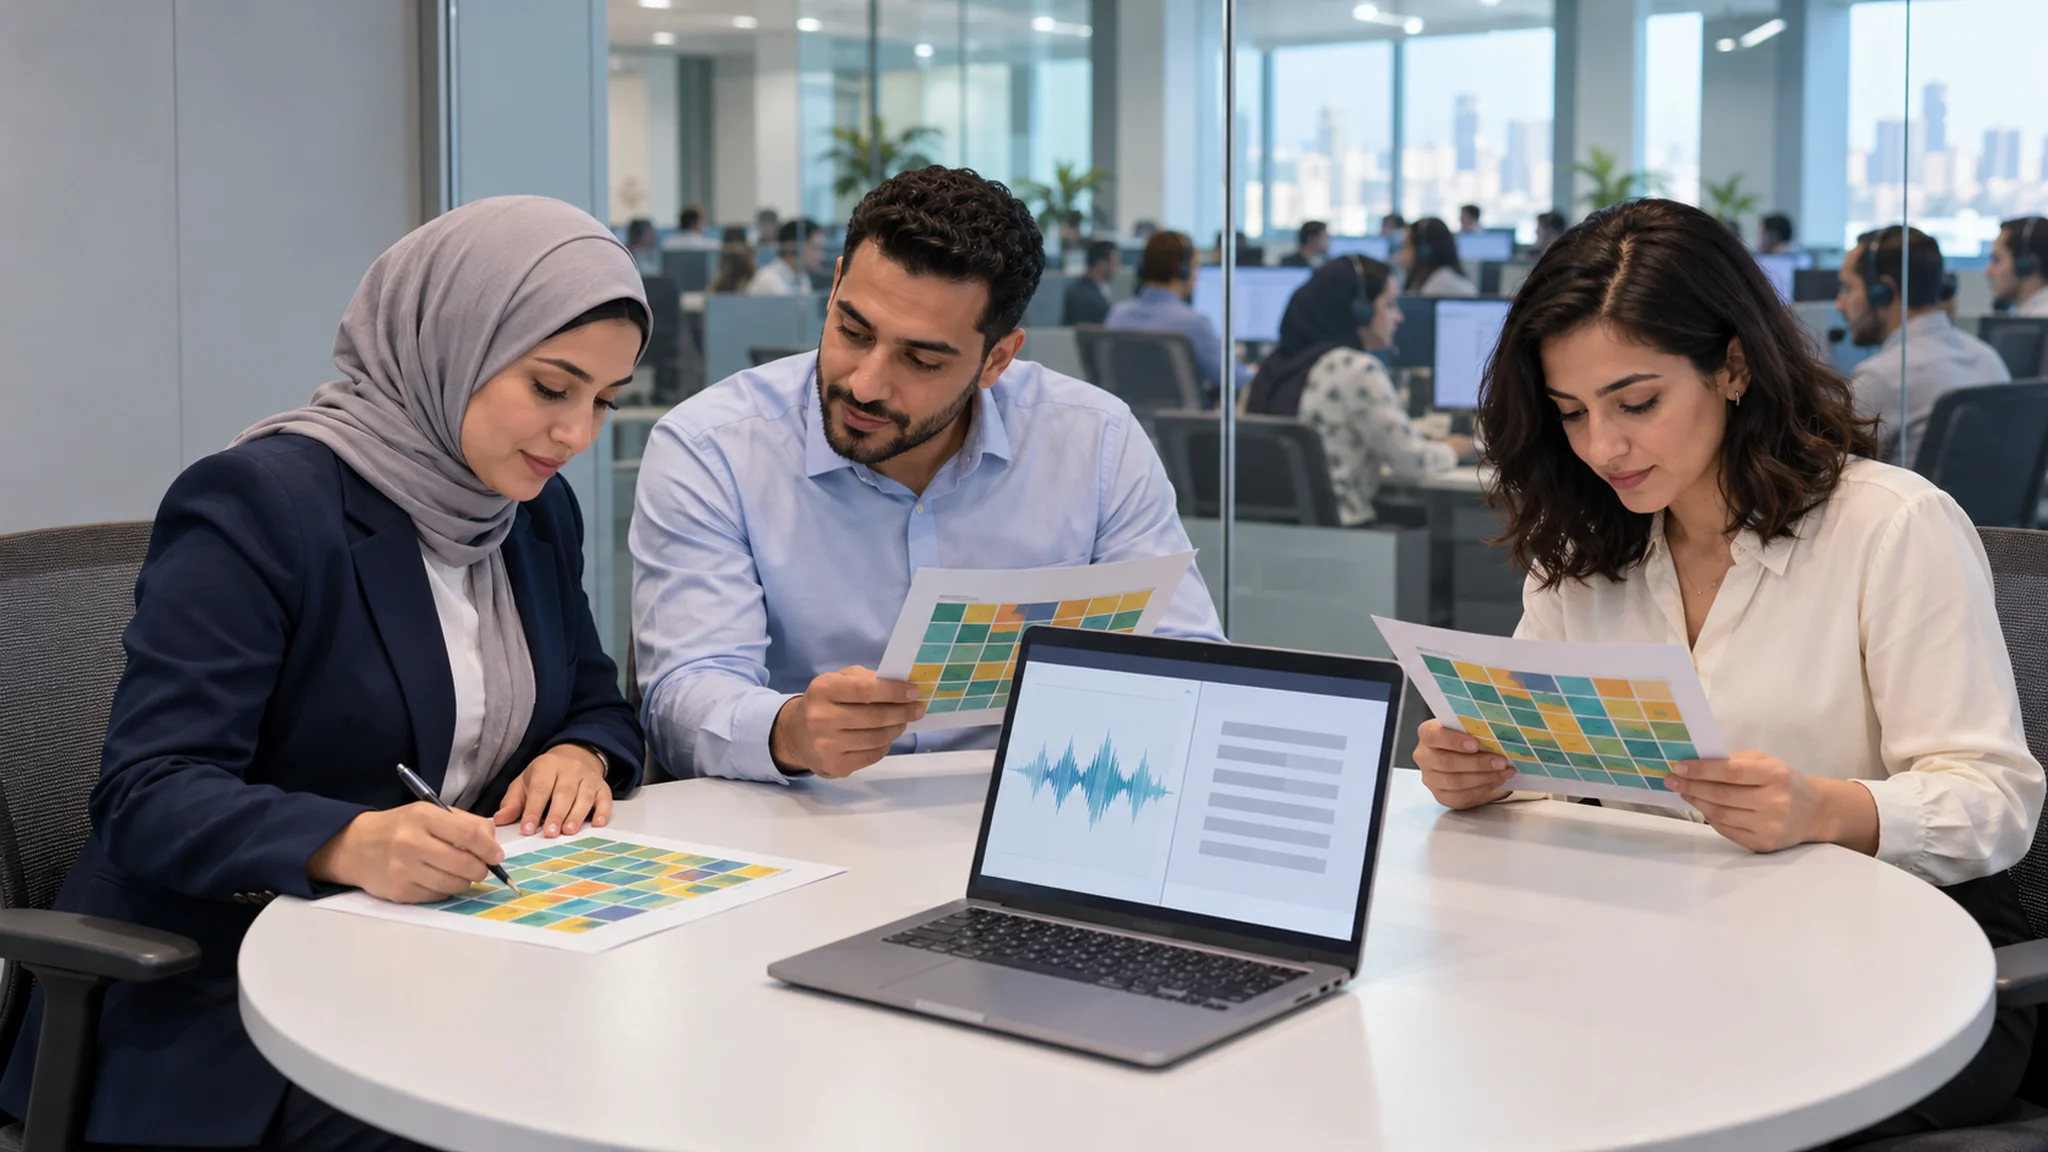
Picture a quality analyst in a Cairo contact center who listens to a sample of calls each week, reads a batch of chats and fills in a form: empathy 3 out of 5, resolution 4 out of 5, language 3 out of 5. The agent sees the numbers a few days later. What they rarely see is what a 5 would have sounded like, or what to change in the next reply.
Meanwhile, the customer service eLearning module covers courtesy, empathy and first-contact resolution in slides, followed by a quiz. Agents pass it easily, and response quality stays where it was. Knowing the definition of empathy is not the same as writing a reply that a frustrated customer reads as respectful, accurate and useful.
This article shows HR and digital learning teams in Egypt how to build eLearning in which agents produce real written and spoken responses and score them against one scorecard, with language versions tailored to each team. The aim is a single picture of response quality that the learning team, the team leaders and the quality team all share.
Why eLearning for Response Quality Needs Production, Not Recognition
A good response does several things at once. It shows the customer was understood, gives correct information, states a clear next step, strikes the right tone and uses language the customer can follow. Agents learn to recognize these features quickly; producing all of them in a live reply, under time pressure, is much harder.
That is why eLearning for response quality should end with agents writing or saying their own reply. Choosing the best of three replies is useful early practice, and our article on building a complaint decision activity for eLearning in Morocco shows how to design it. The step that follows, and the one this article covers, is producing the response and having it scored.
One Scorecard for Written and Spoken eLearning Responses
The scorecard is the backbone of the eLearning. Keep it short, with a shared core that applies to every channel and a few items specific to writing or speaking.
Core Criteria for Every Response
• Understanding: the response restates the customer’s issue accurately.
• Accuracy: the information and the policy applied are correct.
• Next step: it states what happens next, who does it and by when.
• Tone: respectful and suited to the customer’s situation, without empty phrases.
• Language: the agreed language and register for this team and channel.
Channel-Specific Criteria
Written responses add structure (the answer comes first), length, spelling and template hygiene, such as no leftover names from a previous case. Spoken responses add the opening, acknowledging the problem before solving it, pace and clarity, handling holds, and a closing check that the customer has what they need.
Describe three levels for each criterion in observable terms. For the next step, for example: missing; vague, as in ‘we will look into it’; or specific, as in ‘I have opened a request, and a technician will call you before 6 pm tomorrow’. U.S. federal plain language guidance on Digital.gov makes a related point: active voice makes it clear who should do what. Finally, mark a small number of critical items, such as wrong information or sharing another customer’s details, that fail a response whatever its other scores.
A well-built rubric pays off for agents and managers alike. Carnegie Mellon University’s Eberly Center guidance on rubrics notes that rubrics make performance expectations explicit, help ensure consistency across graders and, through component scores, show which skills need more work.
Language Versions of the eLearning by Team
An Egyptian service operation may run several teams under one roof: an Arabic voice team speaking Egyptian Arabic, a chat or email team writing in simpler formal Arabic, and teams serving customers abroad in English or other languages. Customers may also write in Arabic, in English or in Arabic typed with Latin letters, often called Franco. One scorecard can serve them all if you separate what is fixed from what is adapted in the eLearning content:
• Fixed: the criteria, the levels and the critical items, so a ‘specific next step’ means the same in every team.
• Adapted: the wording of the descriptors, the model responses, a short bank of openings and closings, and the register rules, for example when an agent may reply in colloquial Arabic and how to answer a message written in Franco.
Write each team’s eLearning model responses natively rather than translating them, and ask a senior agent from that team to review them. A translated model answer often sounds stiff, and agents learn to imitate the stiffness. Then check the versions against each other once: a bilingual quality analyst scores the same scenario answered in two languages to confirm that each level means the same thing in both.
Turning the Scorecard into an eLearning Practice Loop
With the scorecard in place, each eLearning practice round follows the same loop:
• A realistic customer message, or a short audio clip of a caller, built from invented details rather than real customer records.
• The agent types a reply or records a spoken one, within a time limit close to real handling.
• The agent scores their own response against the scorecard.
• The eLearning then shows a model response annotated criterion by criterion.
• Team leaders score a sample of submissions and add one comment on the weakest criterion.
• The next scenario targets that criterion.
Self-scoring before seeing the model makes agents read the scorecard closely, and the gap between their score and the team leader’s becomes a useful conversation. Keep eLearning scenarios short: one message or a ninety-second call segment is enough to practice most criteria.
Sequence them from calm requests to angrier customers, and from single issues to combined ones, so agents meet the hardest tone decisions once the basic criteria feel familiar. Before adding voice practice, check that your platform can capture audio and route it to a reviewer; our guide to what training managers actually need from an Arabic LMS in Egypt covers that kind of requirement.
Calibrating the People Who Score eLearning Responses
Feedback is only as consistent as the people giving it. Once a month, ask team leaders and quality analysts to score the same five responses independently, compare their scores criterion by criterion and discuss the largest differences. Where disagreements keep recurring, rewrite the descriptor, not just the score. It also helps to track each scorer against the group: a team leader who is always a level stricter or more lenient than colleagues is usually reading a descriptor differently, and a short side-by-side review tends to fix it.
Use the same scorecard in eLearning practice and in live quality reviews. If the floor form still rates ‘empathy out of 5’ while the eLearning scores ‘next step: specific’, agents will learn to satisfy whichever one their manager checks.
A Hypothetical Example: Late Deliveries for an Online Retailer
The following example is hypothetical and only illustrates the approach.
An online retailer serves customers through an Arabic voice team in Cairo, an Arabic chat team in Alexandria and an English email team for customers abroad. Late deliveries are the most common reason for contact, and quality reviews show replies that apologize warmly but leave customers unsure what happens next. That makes late deliveries the obvious starting point for eLearning.
The learning team builds eight eLearning scenarios around late orders: a parcel held at a sorting hub, an incomplete address, a promised date already missed and a customer asking for a refund instead. Each team receives the same scenarios in its own language version, with model responses written by its senior agents. The voice team records spoken replies; the chat and email teams type theirs.
In the first month of the eLearning, self-scores are consistently higher than team leader scores on the next-step criterion, and the most common gap is a missing time frame. The team adds three scenarios focused on giving a specific next step, and team leaders start using the same scorecard in their weekly reviews of live chats and calls.
Practical Points for eLearning in Egyptian Service Teams
Shifts and Noise
Contact centers often run long shifts and night coverage. Schedule eLearning practice in low-volume hours, keep each round under fifteen minutes, and provide a quiet space or a good headset for voice recordings, so agents are not recording over a busy floor.
Recordings and Customer Data
If you want to use real calls or chats as starting points, rewrite them with invented details or re-record them with colleagues, and follow your organization’s data protection requirements. Agent recordings made during eLearning practice also need clear rules on who can listen to them and how long they are kept.
Summary
Response quality improves when agents practice producing responses, not only recognizing good ones. eLearning built on one scorecard, with a shared core, channel-specific items and language versions by team, gives agents specific feedback and gives managers one shared definition of a good reply.
Start with your most common contact reason, write the scorecard with your team leaders, calibrate the scorers and use the same scorecard in eLearning and in live reviews. The same move from explaining quality to practicing it underpins our guide to turning quality explanations into eLearning decisions in Egyptian factories.
Click here. If you would like to build a response-quality scorecard and the eLearning practice around it for your service teams, the SkillUp MENA team can talk through your requirements with you.